The One-Line Answer, Then the 3 Questions
Here is the whole guide in one sentence: use Excel when the data is small, one-off, and destined for a chart or a stakeholder; use SQL when the data is in a database, too big for a spreadsheet, or you will re-run it. Now the nuance, because real work is never that clean. I have seen analysts build a pivot table on a 2-million-row export and watch Excel crawl, and I have seen analysts write a 40-line SQL query to sort 300 rows that would have taken 20 seconds in Excel. Both were the wrong tool for the job, and both were avoidable.
So instead of memorizing rules, run three questions before you touch anything. Question one: where does the data live right now — in a file I can open, or in a database I query? Question two: how big is it — will Excel handle it without choking? Question three: am I doing this once, or is this a report I will re-run next week? Your answers point you at the right tool more reliably than any 'Excel is better at X' list ever could. This is the same practical framing I use in my data analyst skills guide.
Below I walk through both halves of the answer: the concrete situations where each tool wins, and then the same question solved in both so you can feel the difference. The goal is not to crown a winner — it is to give you a decision you can make in seconds instead of a debate you have to have every time.
When Excel Is the Right Tool
Excel shines in a specific and real place: small to medium data, interactive exploration, and a deliverable someone will read. If you are joining a handful of columns, sorting 5,000 rows, or building a chart to drop into a slide deck, opening Excel is usually the fastest path from 'data' to 'done'. The pivot table, the formulas, the ability to click and see — none of that has a clean SQL equivalent, and it does not need one.
If the data fits in a spreadsheet (a few thousand to a few hundred thousand rows) and it is sitting in a CSV or .xlsx you can open, Excel is the natural first move. You can eyeball it, filter it, and see the shape of the data in seconds. SQL adds nothing when you could just open the file.
You are answering 'what is the sales trend here?' once, for a meeting, and you will likely not run this exact analysis again. Excel's speed of iteration — sort, filter, pivot, chart — is unbeatable for a single exploration. Reaching for SQL to do a one-time visual exploration of a small file is often more setup than the answer is worth.
When the end product is a visual — a chart in a deck, a formatted table in an email, a dashboard a non-technical stakeholder opens — Excel is where that deliverable naturally lives. You can format, annotate, and present it directly. Exporting a SQL result to a CSV and re-opening it in Excel to format is a totally normal and smart workflow.
For a quick 'should I just use Excel?' check: if you can sum the whole thing with a pivot table in under a minute and the file is under ~100K rows, Excel is almost certainly the faster choice. I reach for Excel daily for exactly these small, visual, one-off jobs, and that is not a weakness — it is using the right tool.
When SQL Is the Right Tool
SQL is the right tool when the data is not a file you can open, or when it is too big for Excel, or when the analysis will be repeated. The moment the data lives in a database, SQL is not just better — it is the only sane option, because the data is not in Excel and will not be. And once you write a query, that query is a reusable artifact: you run it again next week, next month, on new data, and it produces the same result. That reproducibility is SQL's superpower over Excel.
If the data lives in a database (a data warehouse, a business system, a company DB), SQL is how you get at it. Excel cannot open a database directly the way it opens a file. You might export to Excel, but for anything beyond a quick look, querying in SQL and pulling only what you need is faster and less error-prone than a giant export.
Excel starts to struggle around a few hundred thousand rows and really crawls past a million. SQL databases are built to handle millions and billions of rows. If your analysis touches more than Excel can comfortably handle, do the aggregation in SQL (SUM, GROUP BY, WHERE) and only bring the small result into Excel for the visual. Pulling 2 million rows into Excel to sum them is the fastest way to a frozen laptop.
A SQL query is a repeatable artifact: you can re-run it on fresh data, schedule it, hand it to a colleague, and it does the same thing every time. An Excel analysis lives in your head and your click history — reproduce it next month and you are re-doing the work. For any analysis that repeats (weekly revenue, monthly cohort, daily funnel), writing it in SQL once pays off from the second run onward. This is exactly the reporting pattern I cover in writing SQL for business reports.
The re-run test is the one I use most: if this same question will come up again next week with fresh data, write it in SQL. If it is a genuine one-off, Excel is fine. The sunk cost of learning SQL is repaid entirely by the second time you do not have to rebuild a pivot table from scratch.
The Side-by-Side: Same Question in Excel and SQL
The fastest way to understand the difference is to watch the same business question answered in both. Take: 'what is total revenue per region for 2025, sorted highest first?' The data is a sales table with columns order_id, region, category, amount, and order_date. Watch how the two tools approach it, and you will see why the choice is about the data and the repeat, not about which tool is 'better'.
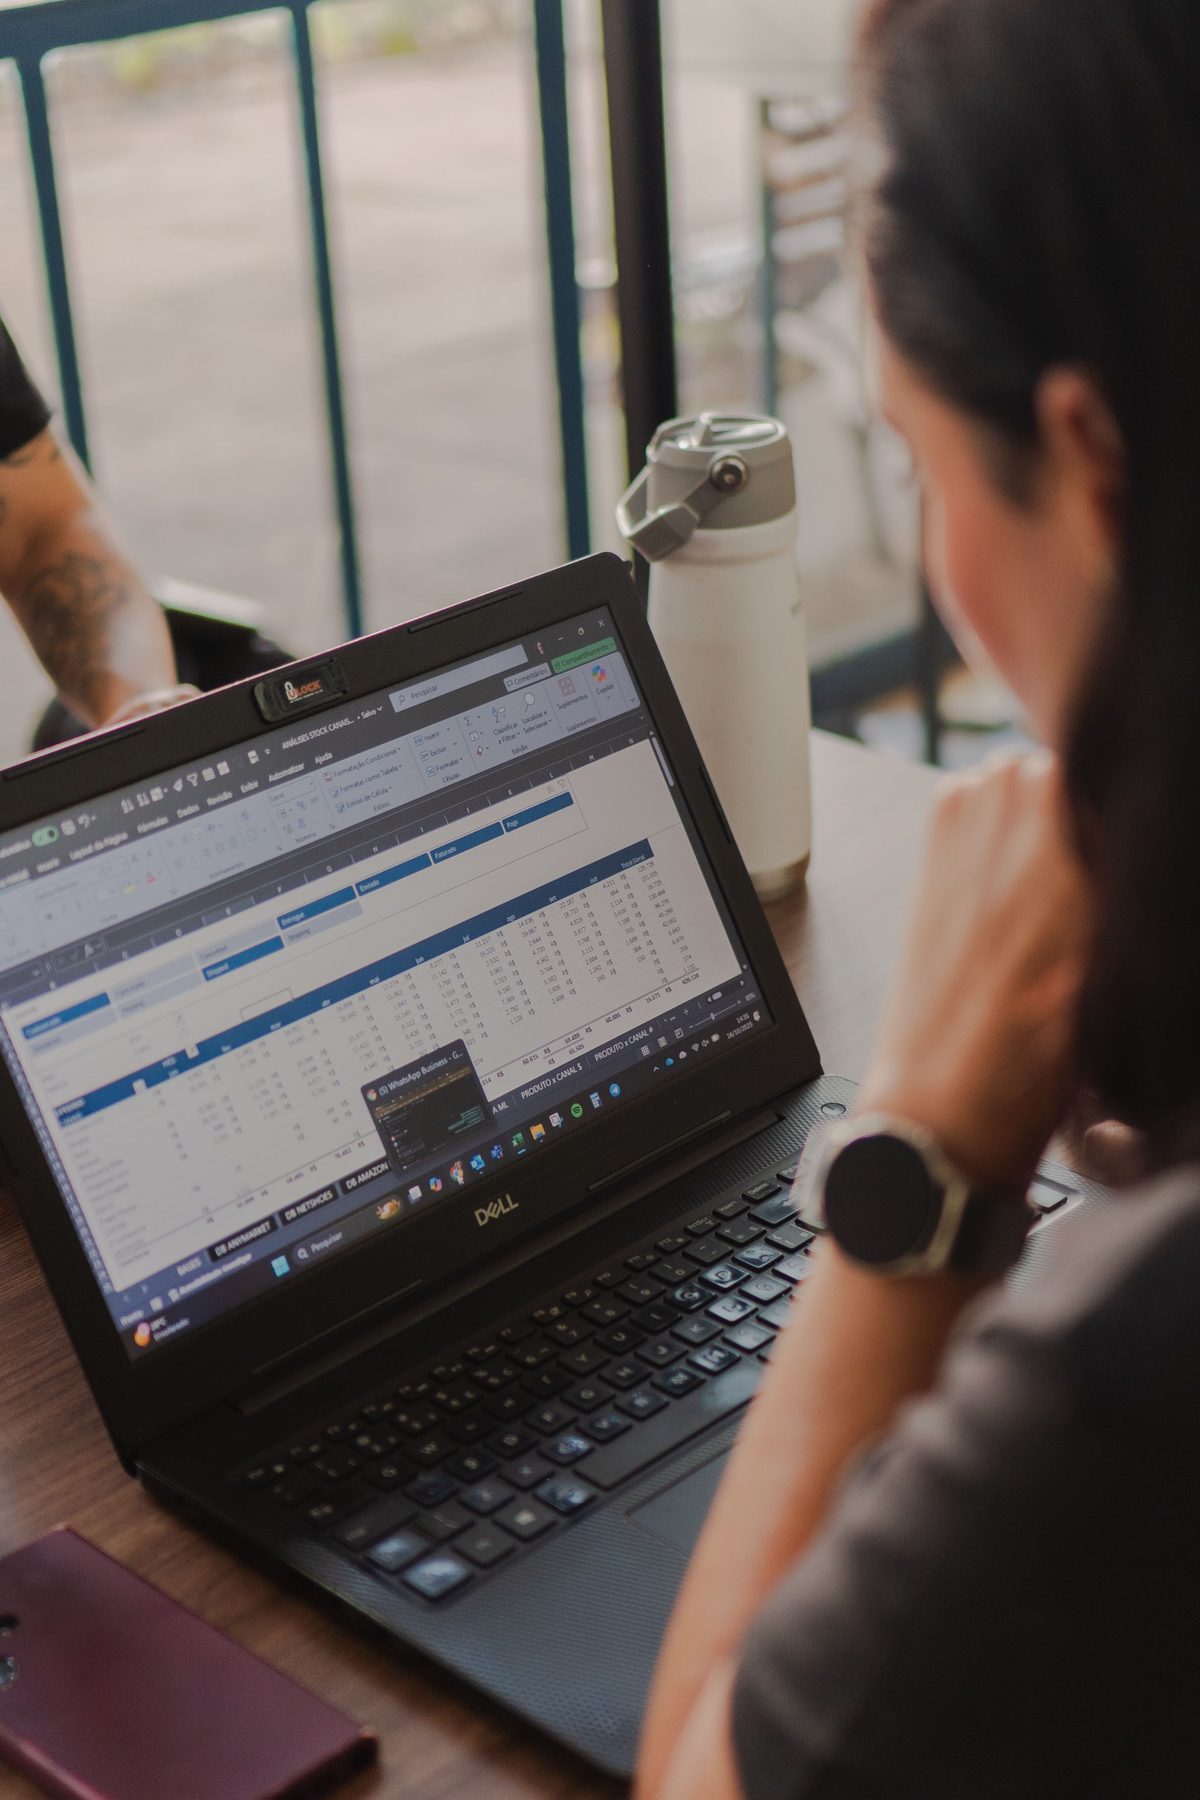
Open the file. Select all the data. Insert a pivot table. Drag region to Rows, amount to Values (set to Sum), add a filter on year 2025, then sort by the total column. About 6 clicks, 30 seconds, and you can see the result immediately and drag it into a chart. For a one-off on a small file, this is genuinely fast and pleasant.
Write: SELECT region, SUM(amount) AS total_revenue FROM sales WHERE YEAR(order_date) = 2025 GROUP BY region ORDER BY total_revenue DESC;. Run it, get the same answer. It took slightly longer to write, but you now have a query you can re-run next month on new data, add a category breakdown to, or schedule. The output is a clean table you can still drop into Excel for the chart.
For the first run on a small file, Excel wins on speed. For the second run, SQL is ahead because the query is already written. Neither is 'the better tool' — they are two speeds for the same question, and the right choice depends on whether you are sprinting once or running a recurring race. That is the whole Excel-vs-SQL debate in one example.
You do not have to pick a camp. The strongest analysts do the heavy aggregation in SQL and finish the visual in Excel — that pipeline is faster than either tool alone. If you already know Excel, the jump to SQL is mostly learning the SELECT / FROM / WHERE / GROUP BY grammar, and my Excel-user's guide to SQL is built for exactly that transition.
The Real Workflow: They're a Pipeline, Not Competitors
In real companies, Excel and SQL are not rival tools you choose between — they are two stages of one pipeline. The database holds the source of truth, SQL extracts and aggregates what you need, and Excel turns the small result into a readable deliverable. Analysts who treat them as complements get more done than analysts who insist one is 'the real' tool. The data flows down: raw and huge in the database, filtered and summarized by SQL, then visualized and shared in Excel.
Query the database with SQL to get exactly the columns and aggregations you need. Keep the query small — pull what you will actually use, not the whole table. This is where you filter, group, and compute so Excel does not have to. A good SQL pull is the difference between a manageable deliverable and a 2-million-row monster.
Take the SQL result (exported to CSV, or pasted) and build the pivot, the chart, the formatting, the annotations that make it readable. This is Excel's home turf — visual polish and stakeholder-facing output. You are finishing the deliverable, not wrestling with scale.
If the report runs weekly, keep the SQL query saved (or scheduled) so the data pull is reproducible, and let Excel just re-render the same chart on the new data. The SQL stays constant, the Excel file refreshes. This is the exact 'weekly reporting stack' I describe in SQL for business reports, and it removes the manual rebuild every time.
Think of it as division of labor: SQL owns 'get me the right numbers reliably', Excel owns 'make this look like something a human can read'. When I see an analyst copy-pasting a 500,000-row query result into Excel to sum it, that is the pipeline in reverse — they are using Excel to do SQL's job. Move the heavy lifting up into SQL and Excel becomes fast again.
How Analysts Actually Decide (My 3-Question Checklist)
Here is the exact checklist I run through when I am about to start an analysis, so the decision becomes a habit instead of a debate. It is not about tool loyalty — it is about finishing the job with the least friction. Run these three questions, and your tool almost always picks itself.
If it is a file I can open (CSV, .xlsx) → Excel is on the table. If it is in a database → SQL, because I cannot open a database as a file. This single question eliminates most of the debate before it starts.
Under ~100K rows and a one-off → Excel. Over that, or over a million → do the aggregation in SQL even if I start in Excel. If Excel would freeze on a full-table sum, the sum belongs in SQL and only the small result comes back to Excel.
One-off exploration → Excel is fastest. Recurring report → SQL, so the query is saved and reproducible. When in doubt, I write it in SQL if there is any chance it becomes recurring — converting a one-off pivot into a SQL query later is more work than writing SQL from the start.
Do not let job-post hype make this harder than it is. Every data analyst job lists both Excel and SQL because both are used daily, in the pipeline described above. The skill is not 'Excel vs SQL' — it is knowing which stage each tool owns. Learn the fundamentals of both and you will never be blocked by the choice again; that is the roadmap I lay out in how to learn data analysis.
Your Excel vs SQL Decision Sheet
Here is the whole thing compressed into one list you can glance at when you are about to start work. Keep it next to you until the three-question habit is automatic.
The data is a small file you can open, the task is a one-off exploration, or the deliverable is a chart/formatting a stakeholder will read. Excel's pivot + visual speed is unbeatable there.
The data lives in a database, the data is too big for a spreadsheet, or the analysis repeats (or others will run it). SQL's reproducibility and scale handling are its superpowers.
Where does the data live? How big is it? Will I re-run it? Answer those and the tool picks itself — file + small + one-off = Excel; database + big + recurring = SQL.
SQL pulls the right numbers reliably, Excel makes them readable. Do the aggregation in SQL, finish the visual in Excel, automate the repeat. That combination beats either tool alone.